Language & Vision Intelligence
Large language models, vision–language models, multimodal understanding and efficient AI.

Connecting learning, perception, and interaction with human needs through interdisciplinary research, real-world studies, and the development of interactive prototypes.
Explore our core research areas and discover selected projects and findings below.
Large language models, vision–language models, multimodal understanding and efficient AI.
Portable sensing, probe tracking and ultrasound reconstruction.
Detection, segmentation, person re-identification and identity consistency.
Contactless sensing, radar-based perception and human activity analysis.
Immersive experiences, spatial displays, eye tracking and human-centered design.
Practical technology with industry, universities and the community.
Select a field to explore related research highlights.
Filter by field and open each study as a full page in the current tab.
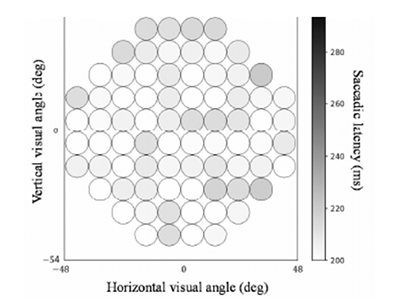
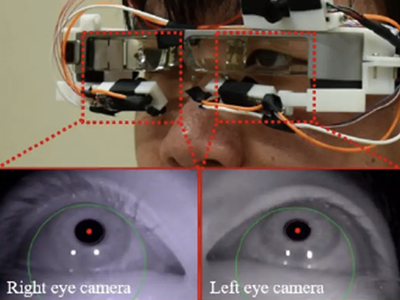
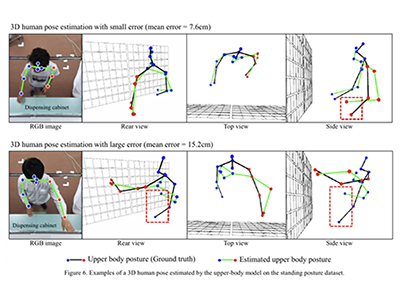
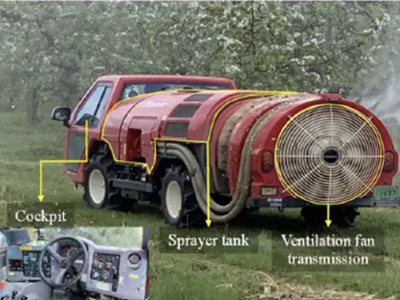
Explore one live prototype at a time. Select Next to discover another demo.
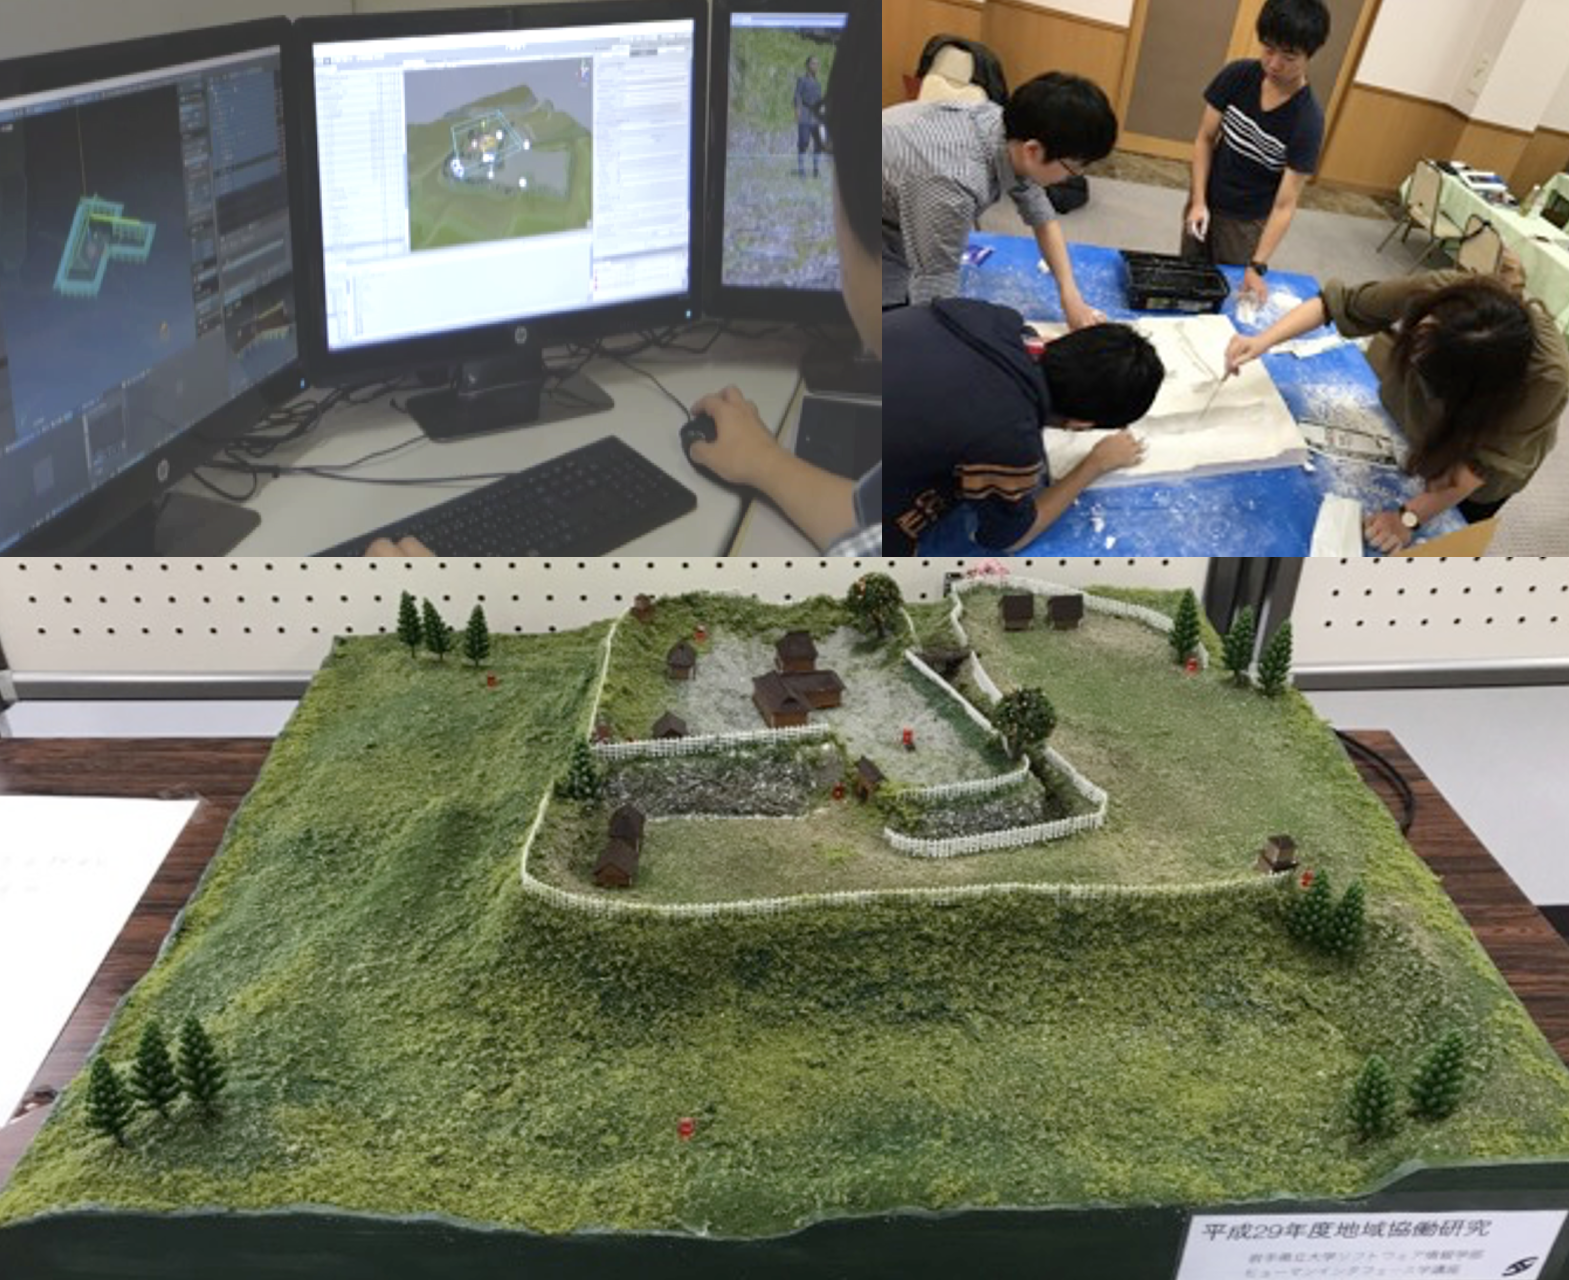
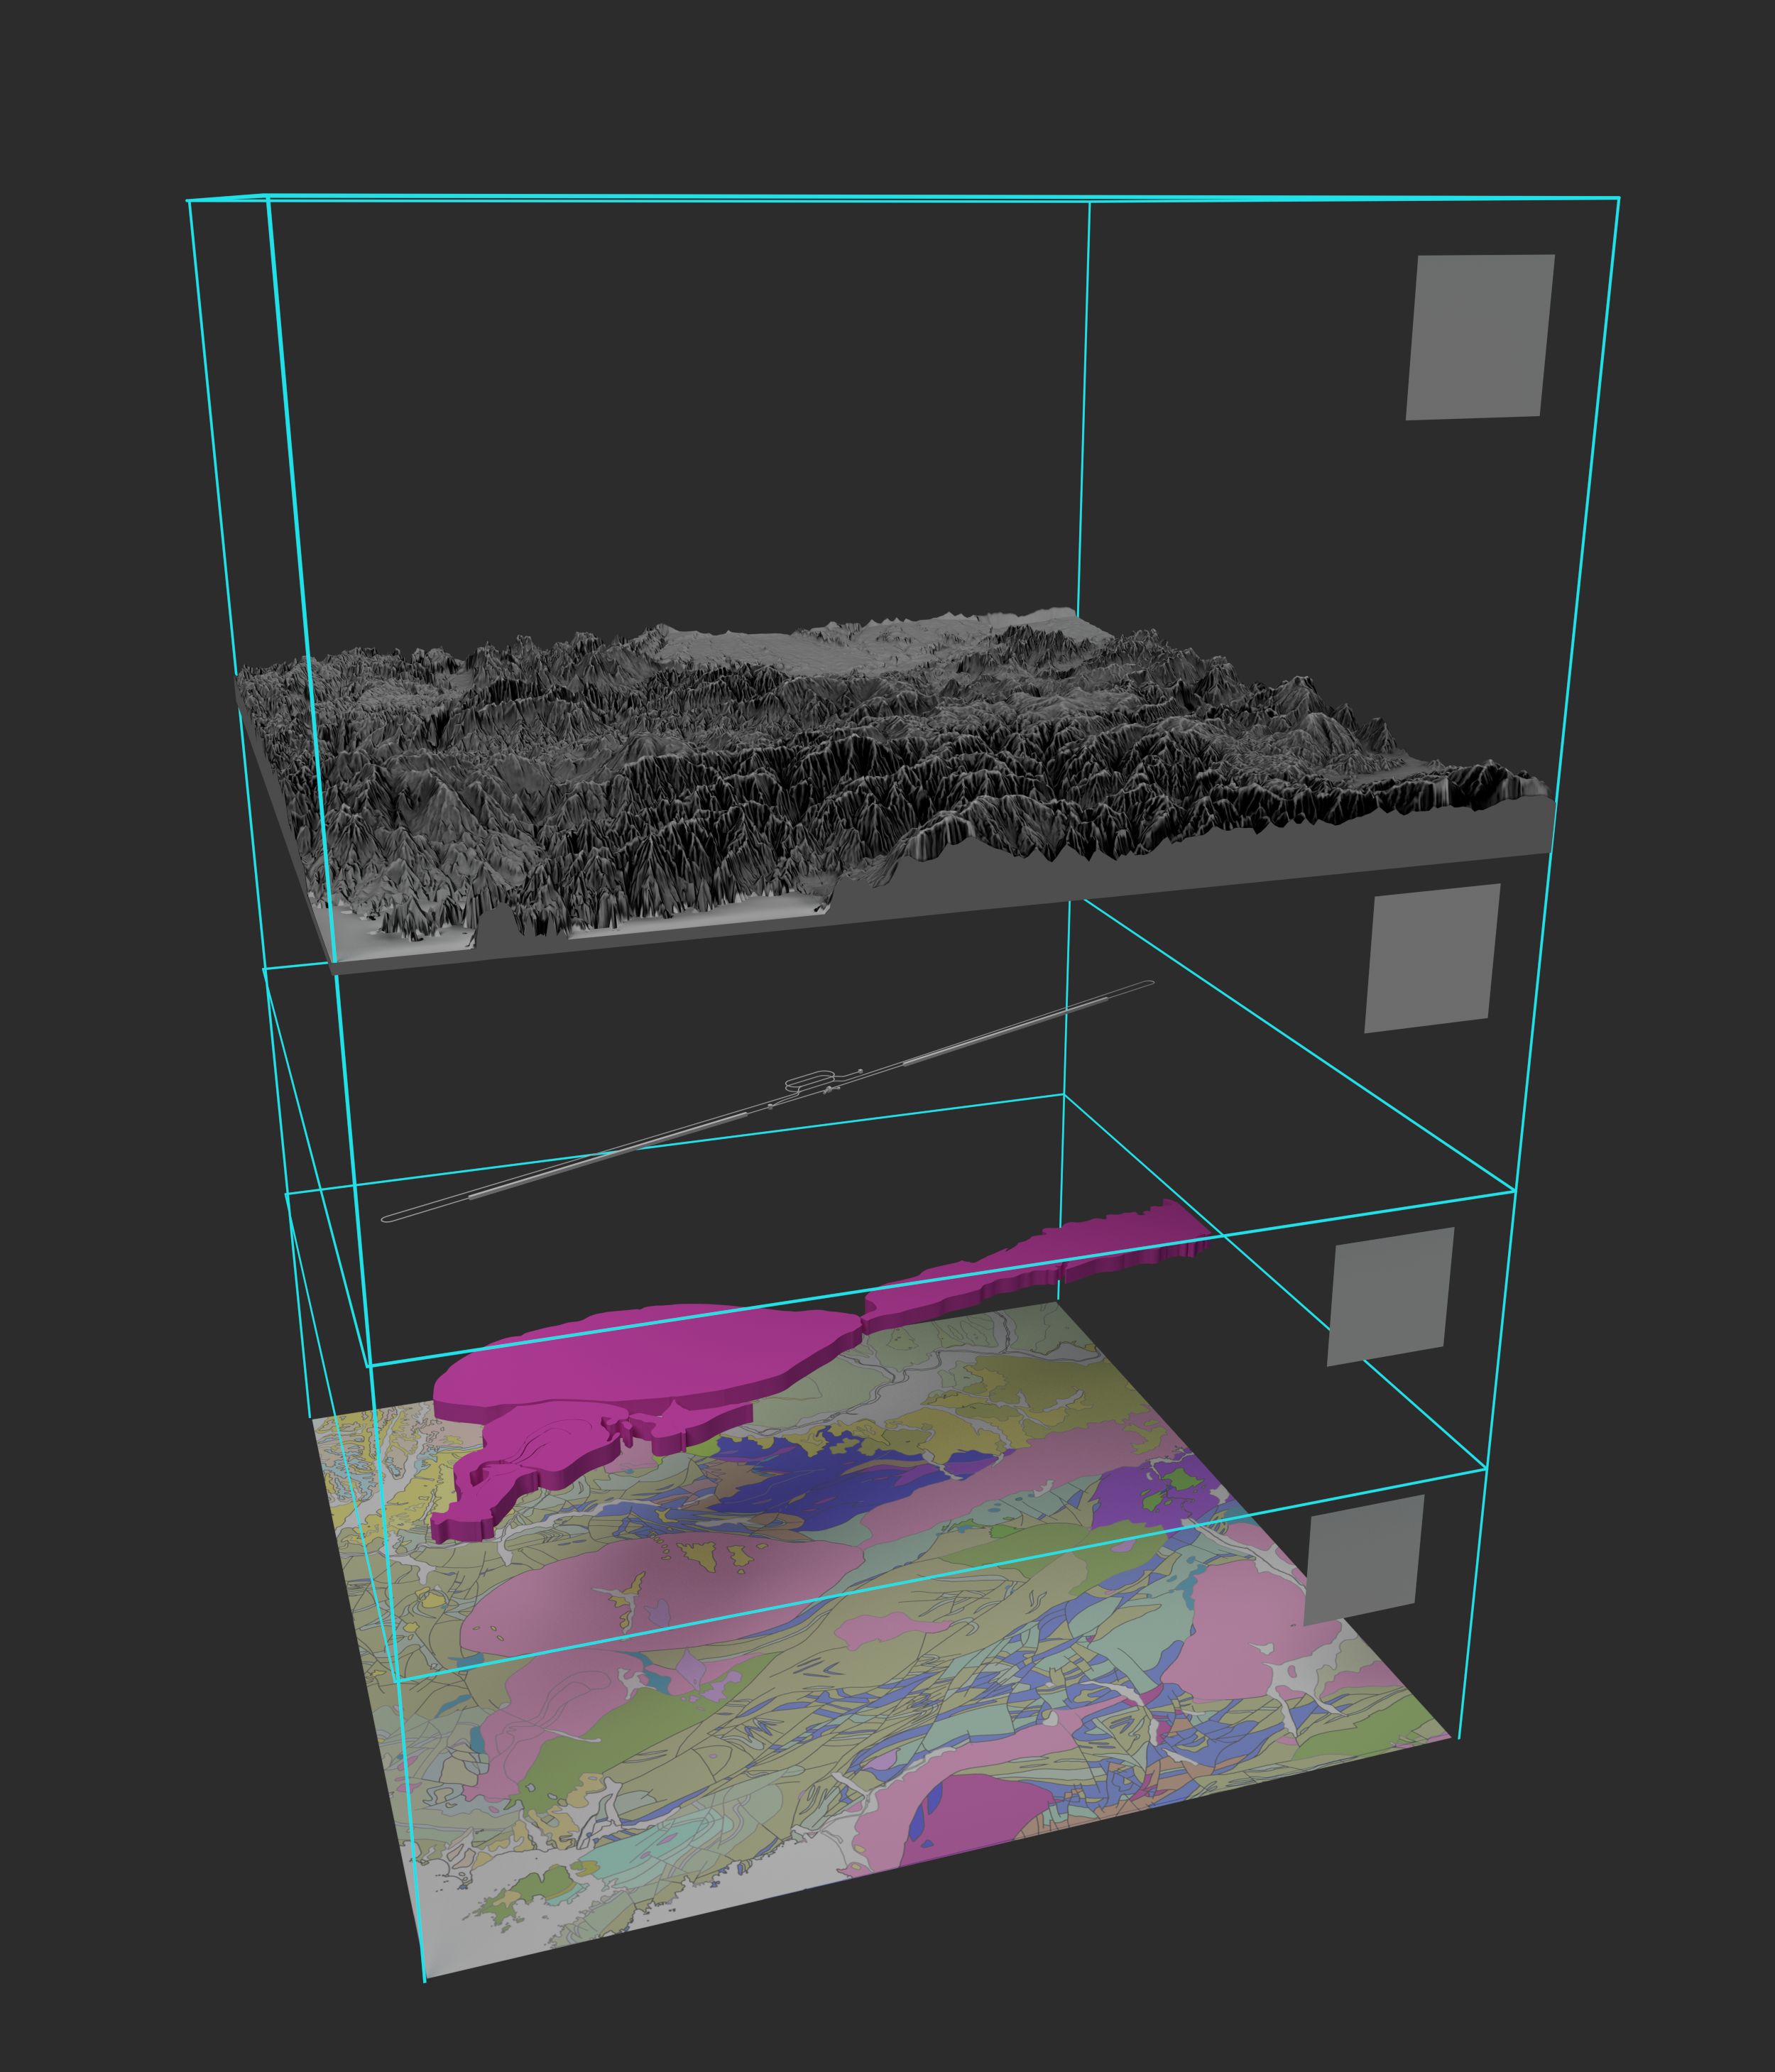
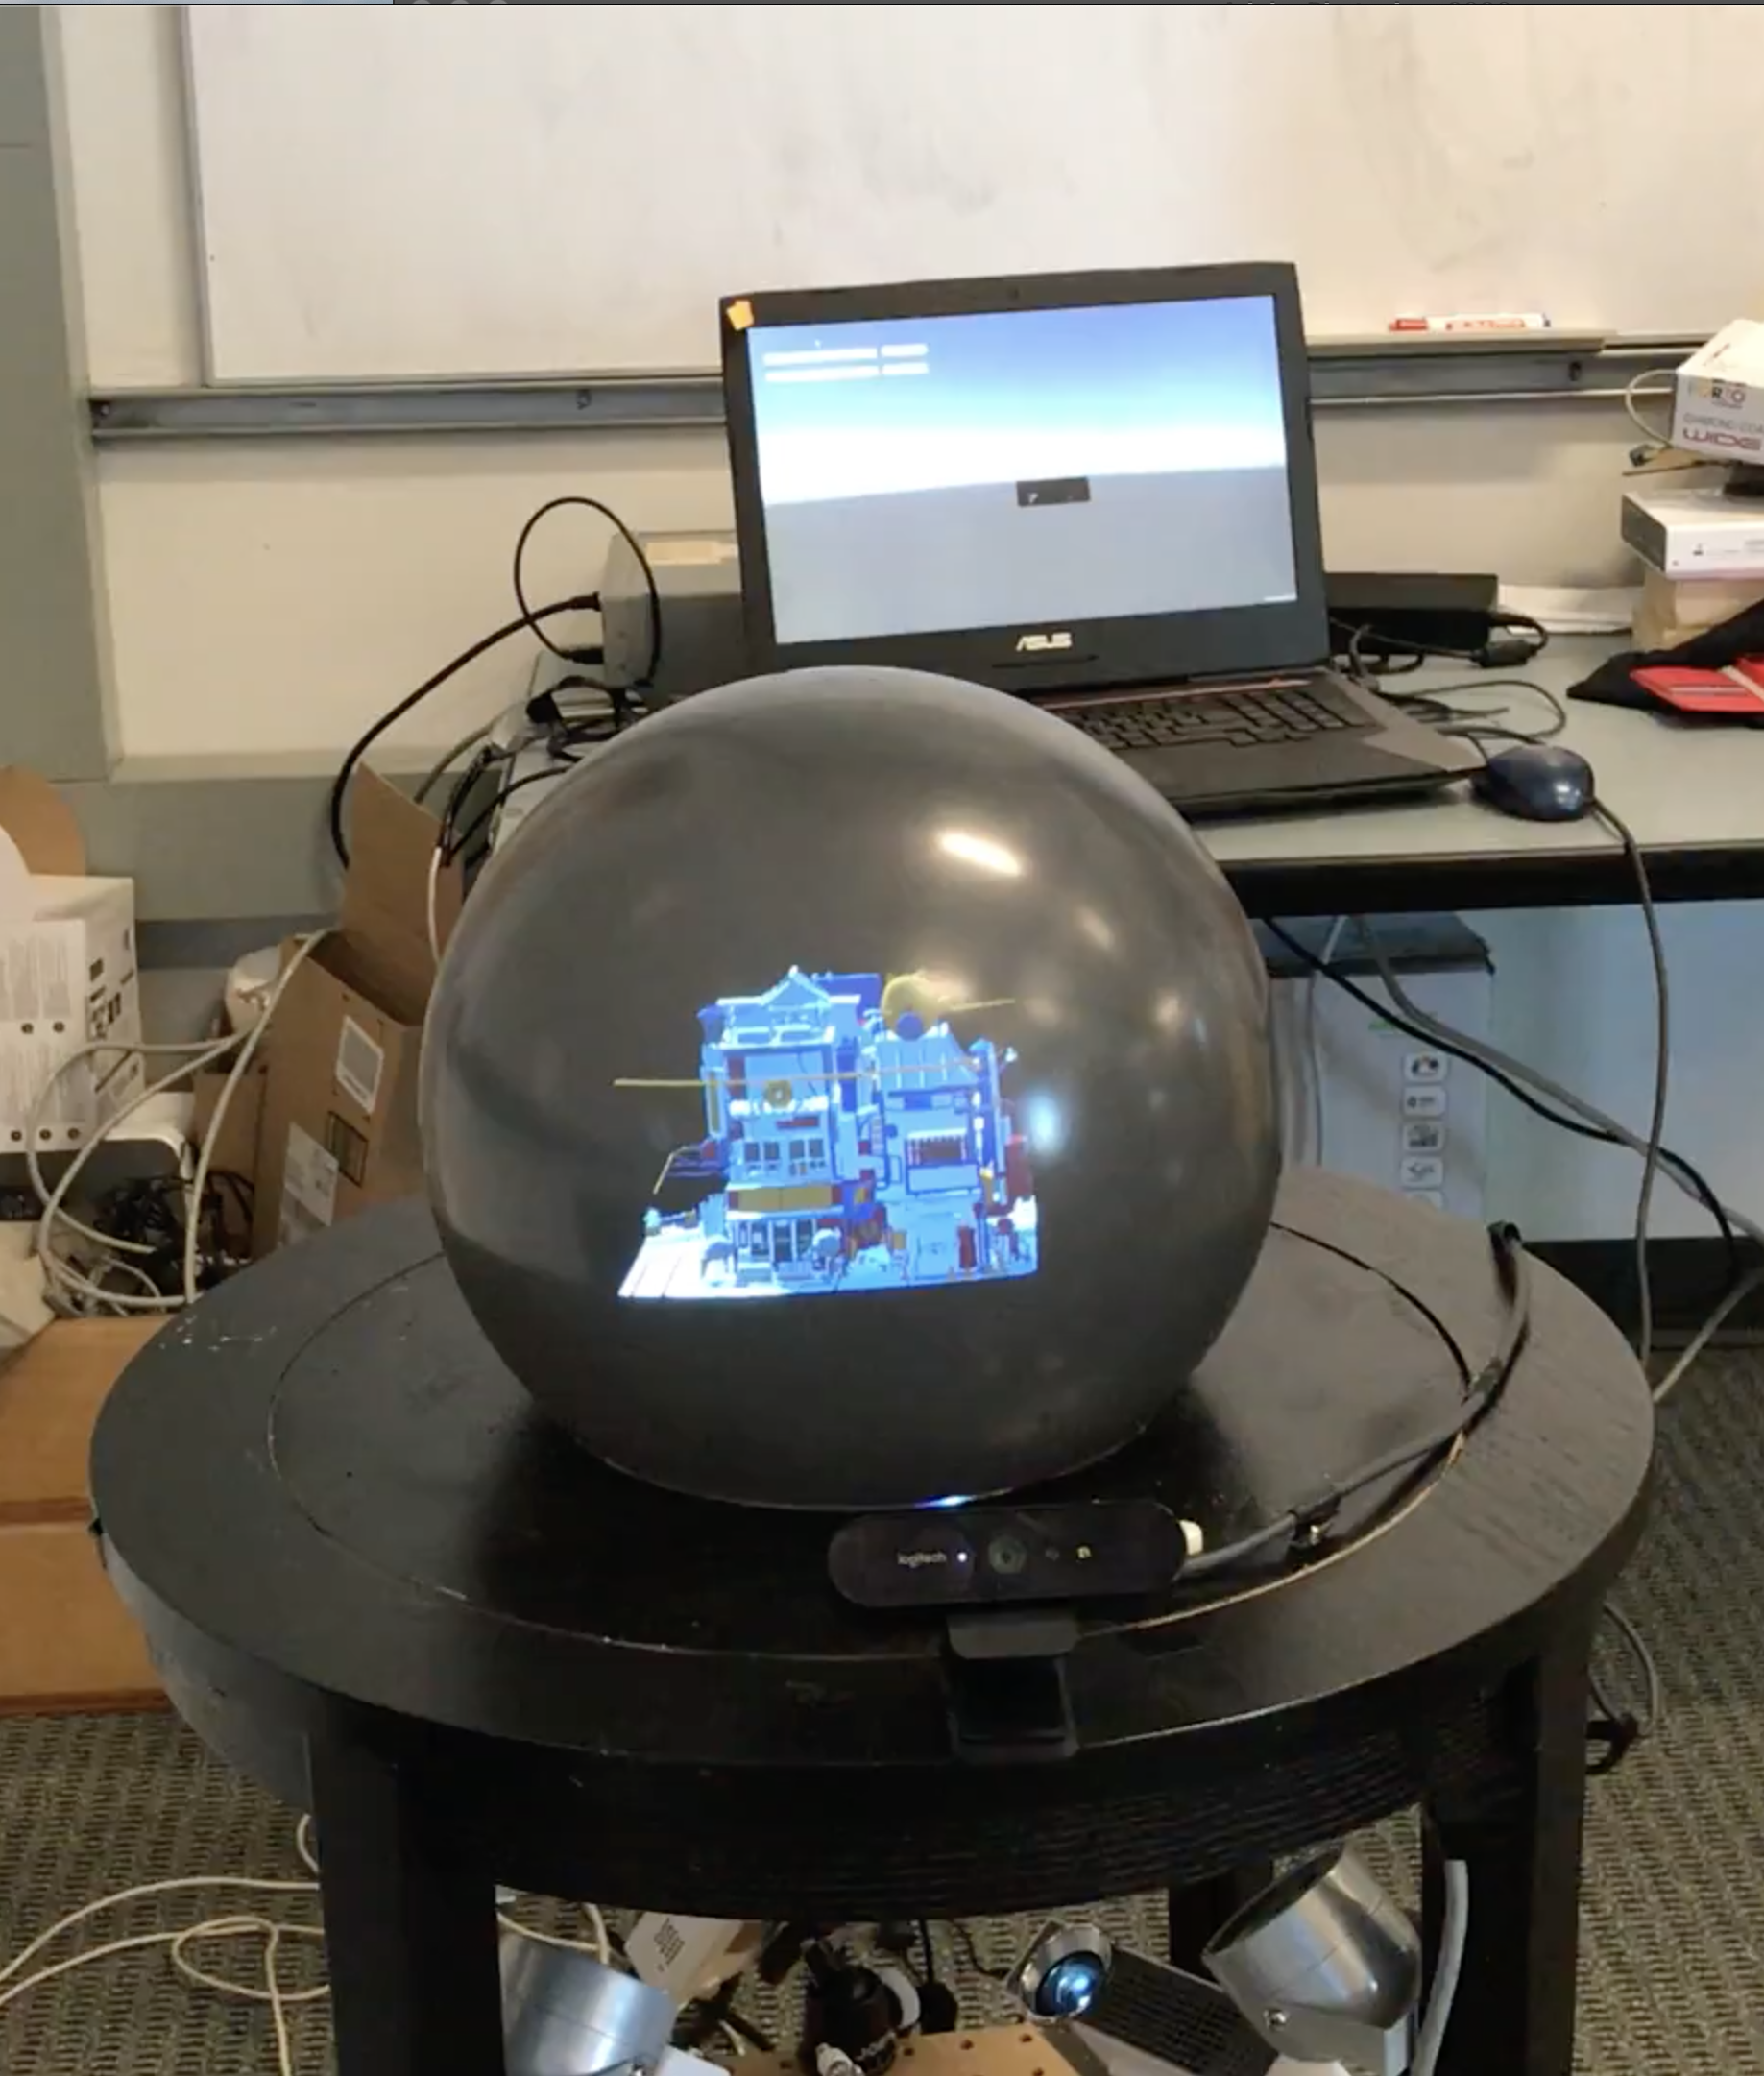
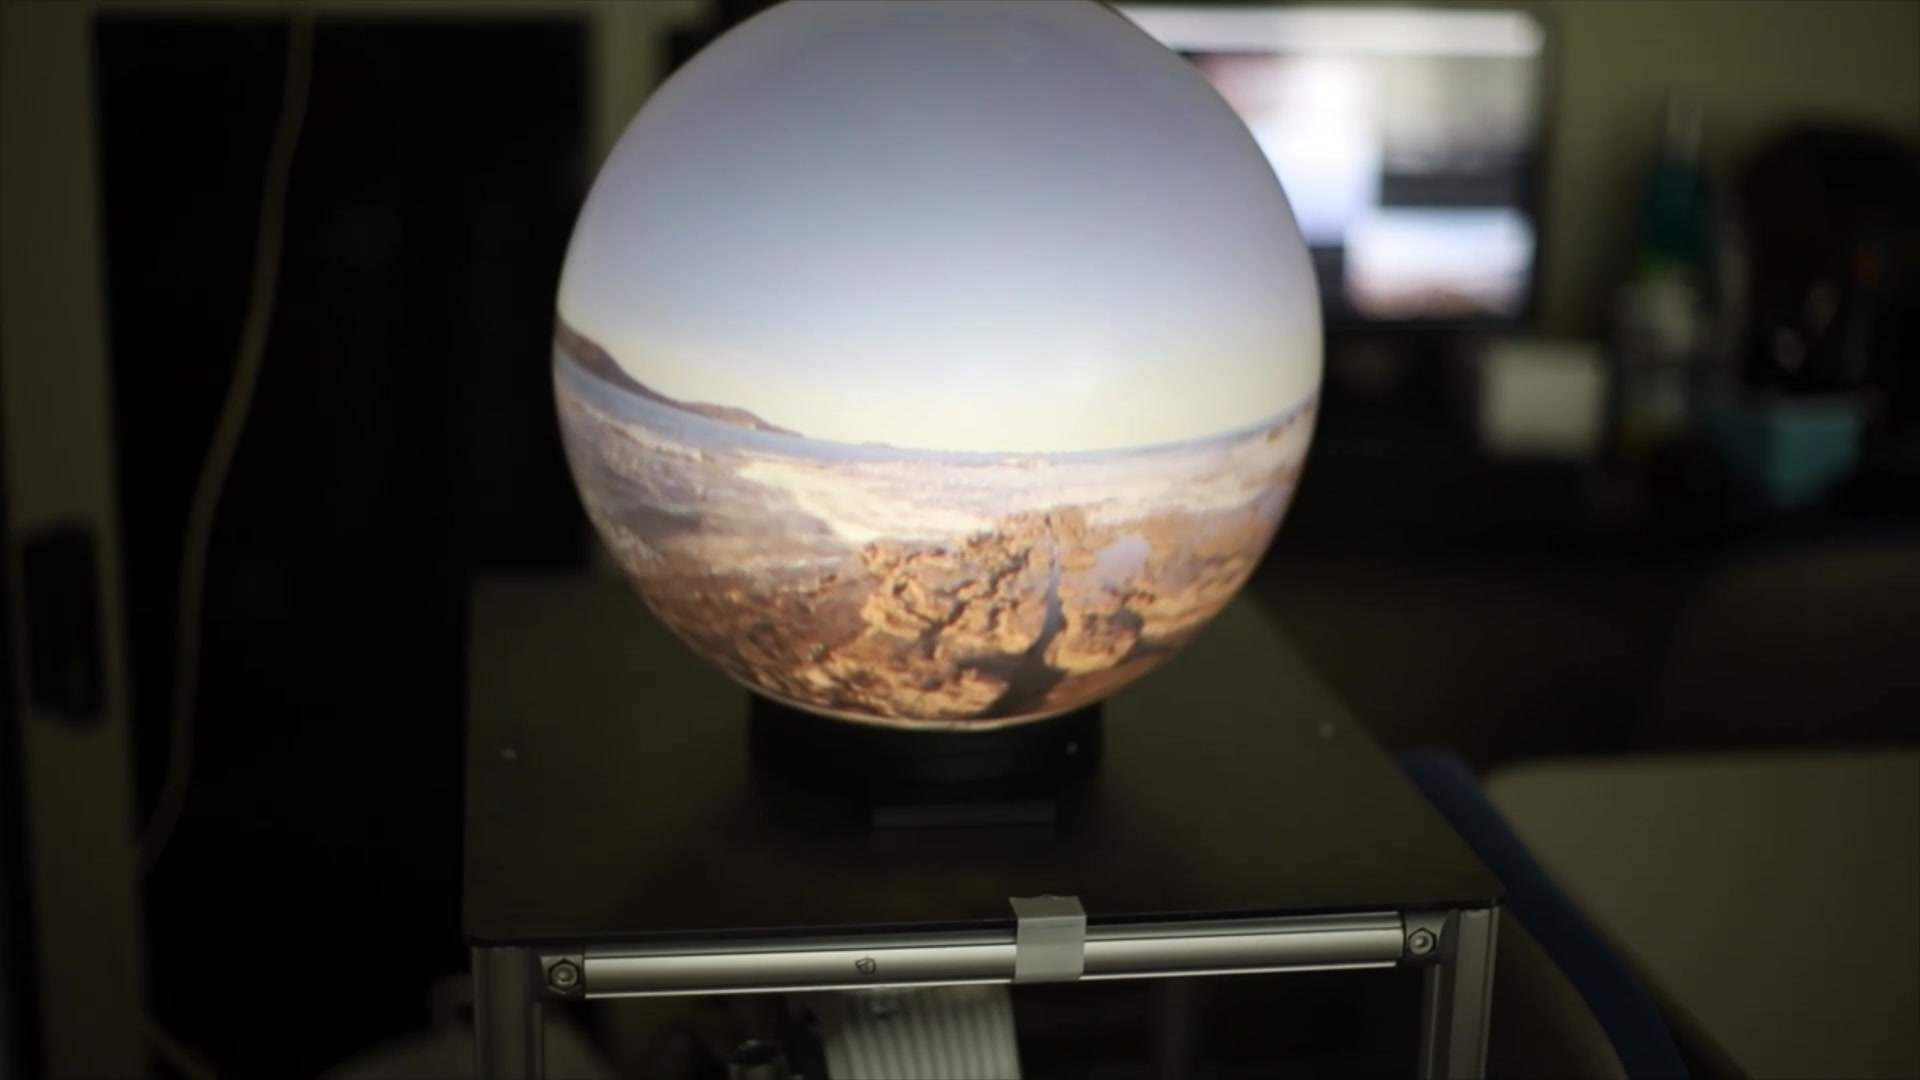
From Kunohe Castle VR and ILC visualization to the SpheriCul spherical display. Below are four moving demonstrations from the original SpheriCul website.
These are the original SpheriCul animations. Press play to watch each demonstration.