Language & Vision Intelligence
Large language models, vision–language models, multimodal understanding and efficient AI.

Connecting learning, perception and interaction to human needs—from research directions to working projects and filmed demonstrations.
Large language models, vision–language models, multimodal understanding and efficient AI.
Portable sensing, probe tracking and ultrasound reconstruction.
Detection, segmentation, person re-identification and identity consistency.
Contactless sensing, radar-based perception and human activity analysis.
Immersive experiences, spatial displays, eye tracking and human-centered design.
Practical technology with industry, universities and the community.
A selection of work spanning healthcare, tracking, visual inspection, sensing and immersive technology.
A dual-rotary-encoder tracking framework for portable, freehand 3D breast ultrasound reconstruction.
Research source ↗Domain adaptation and ensemble fusion for robust person re-identification.
Research source ↗Assessment of spatial perception using cube and light-field displays.
Research source ↗Computer vision for segmentation and detection of small defects in food imagery.
Research source ↗Research themes in mmWave human sensing and multi-sensor perception.
Interactive three-dimensional experiences and human-centered systems.
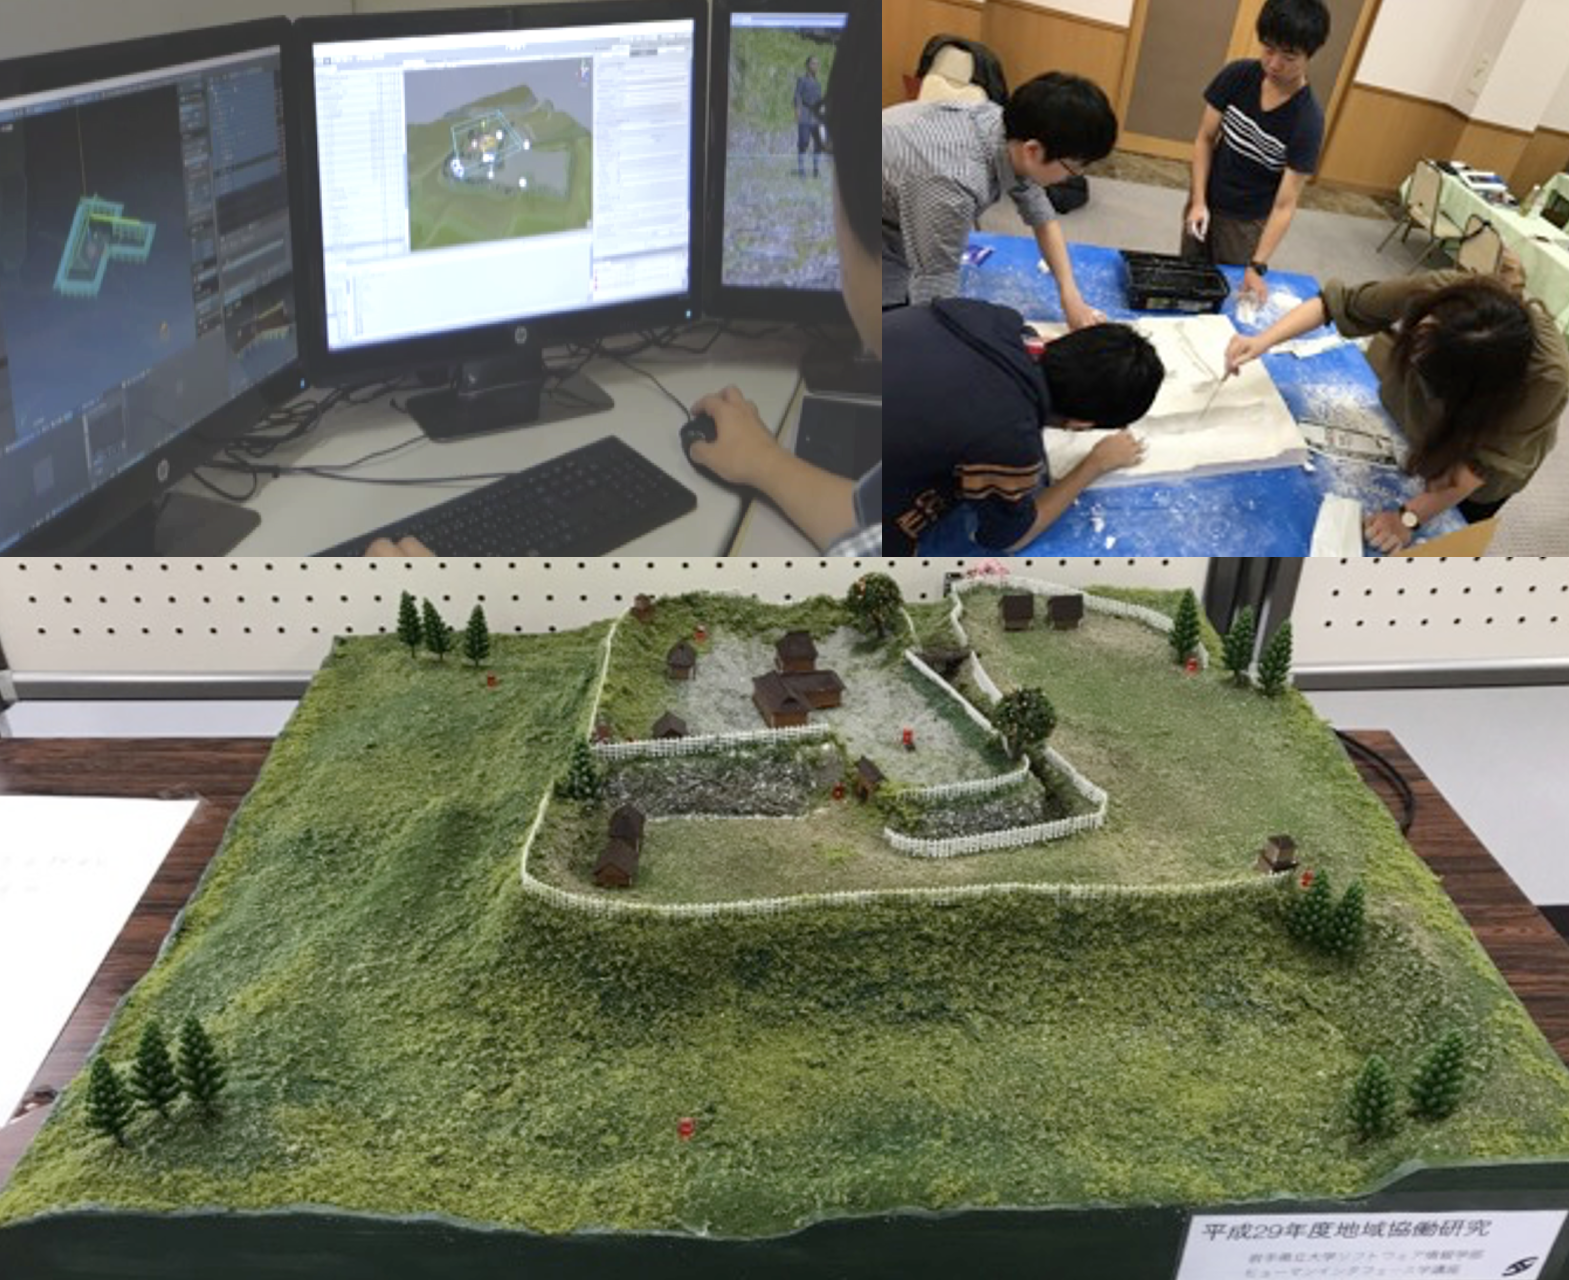
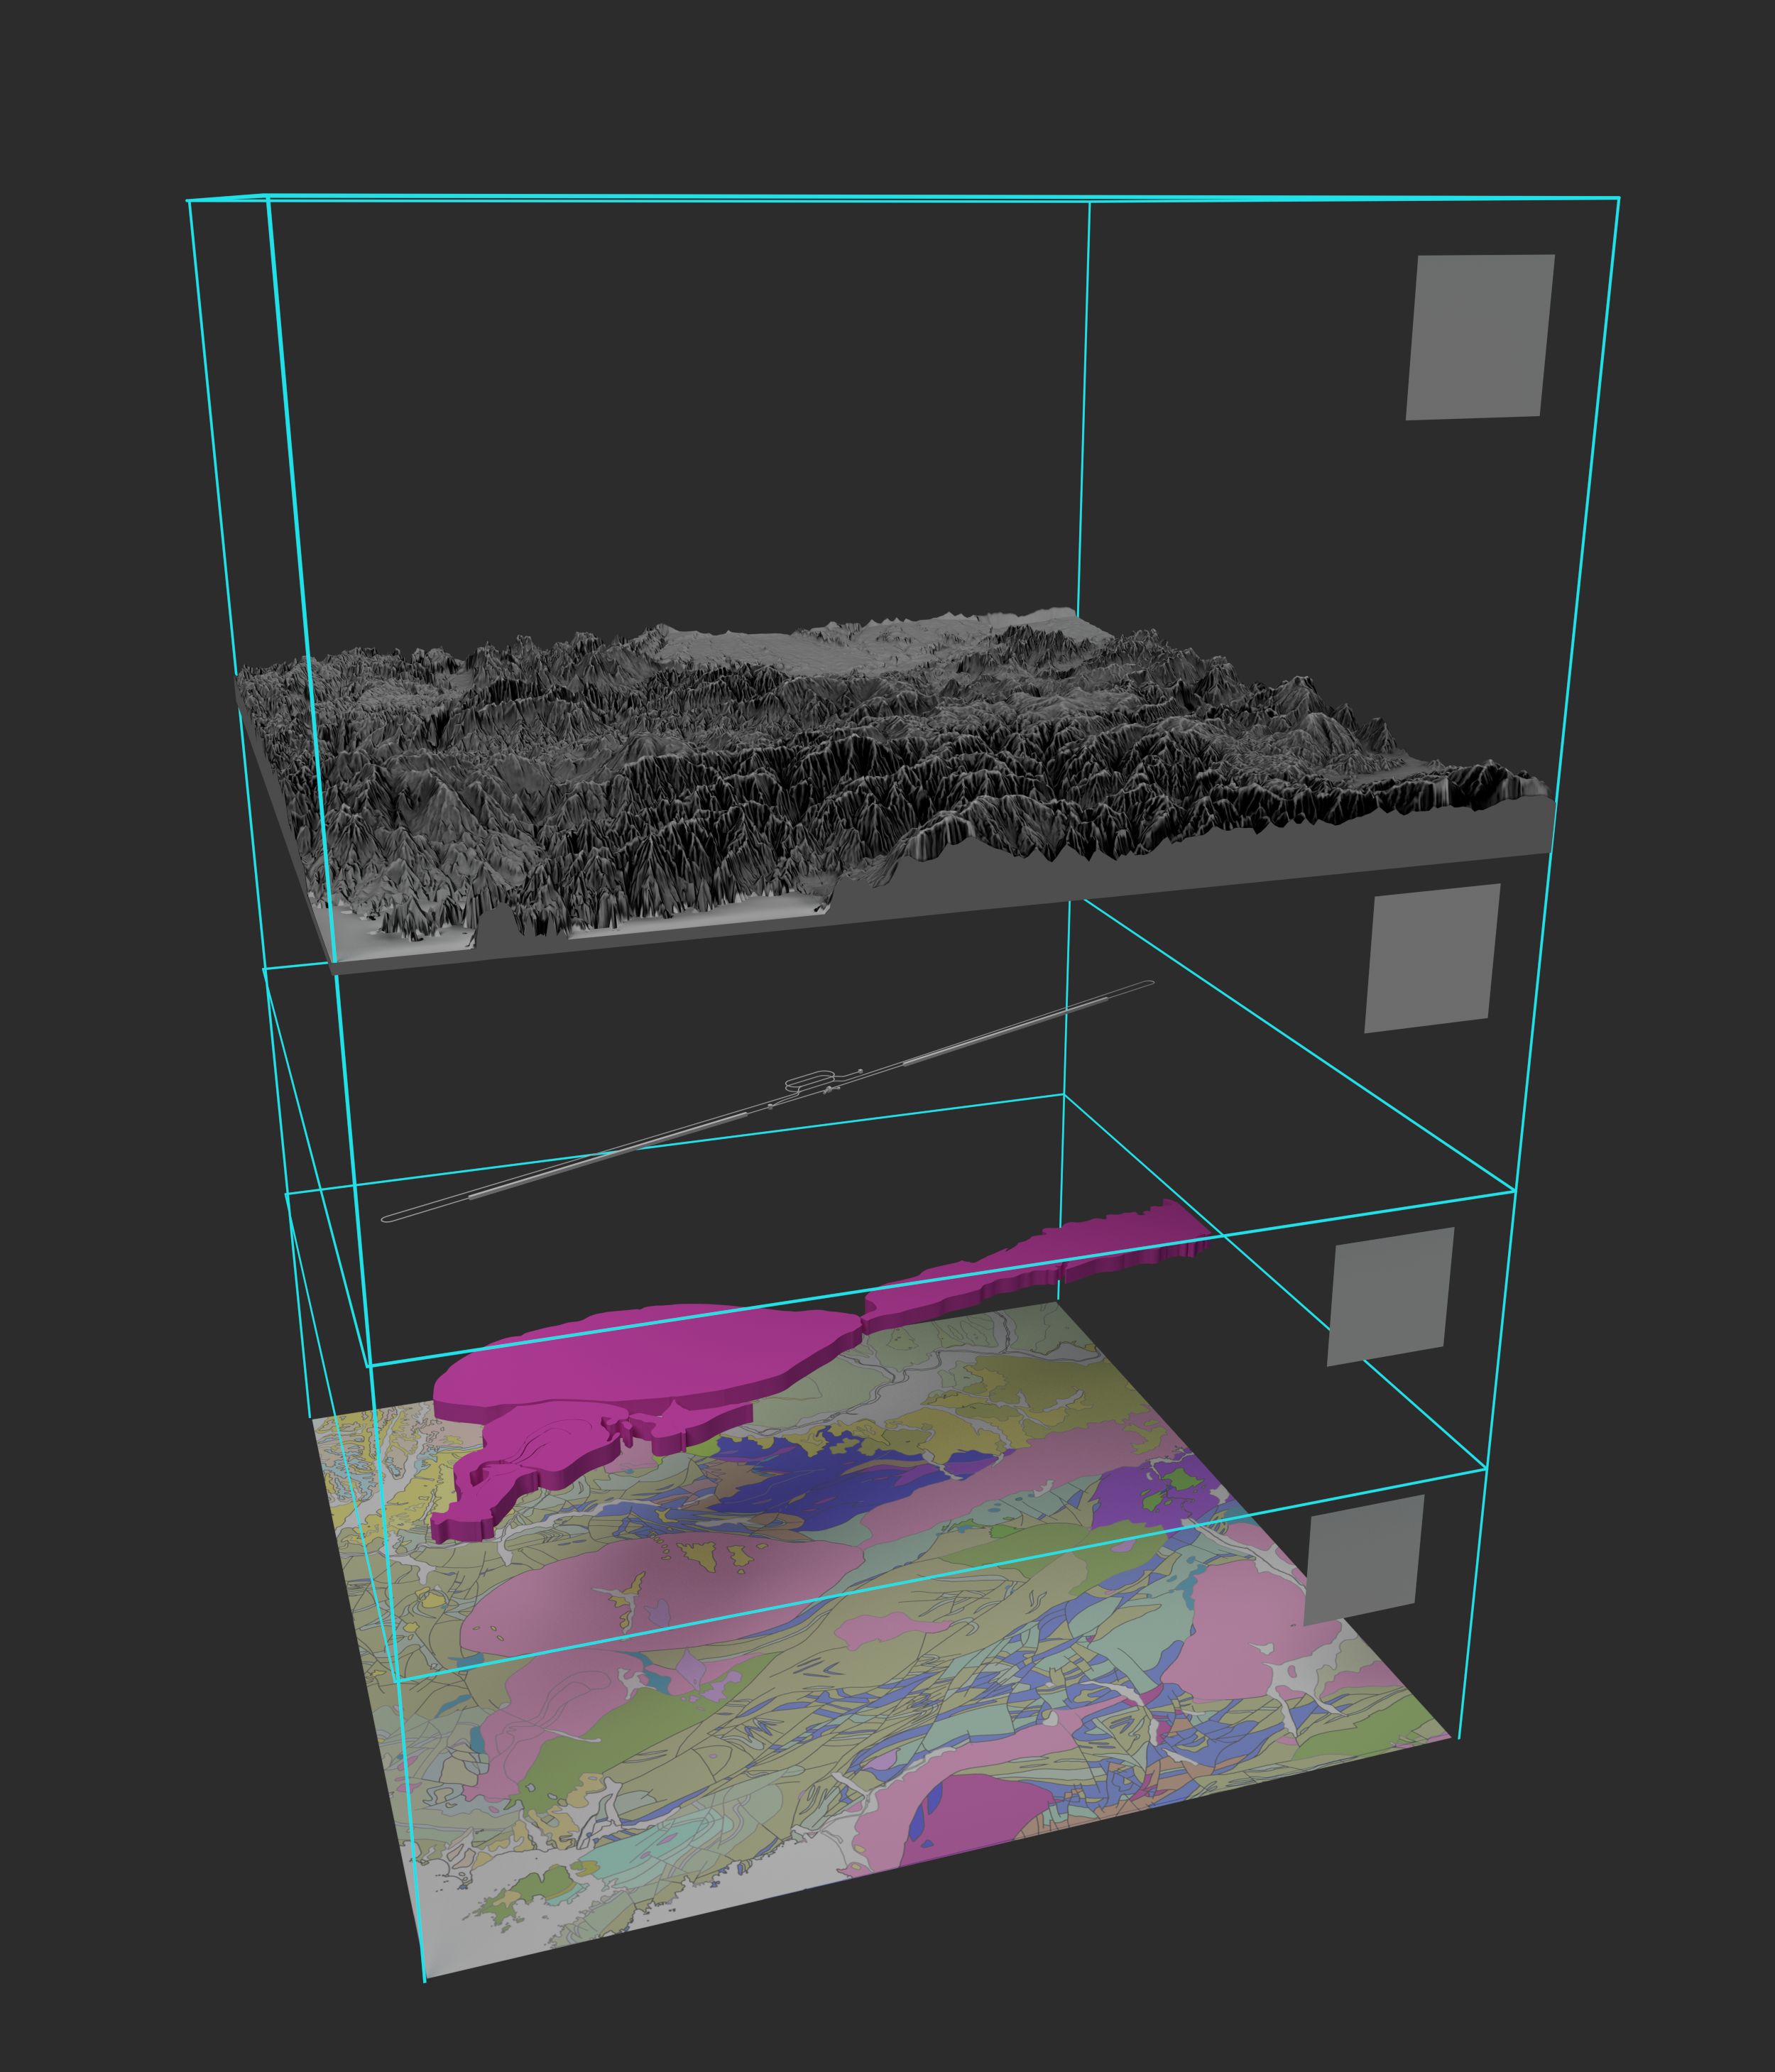
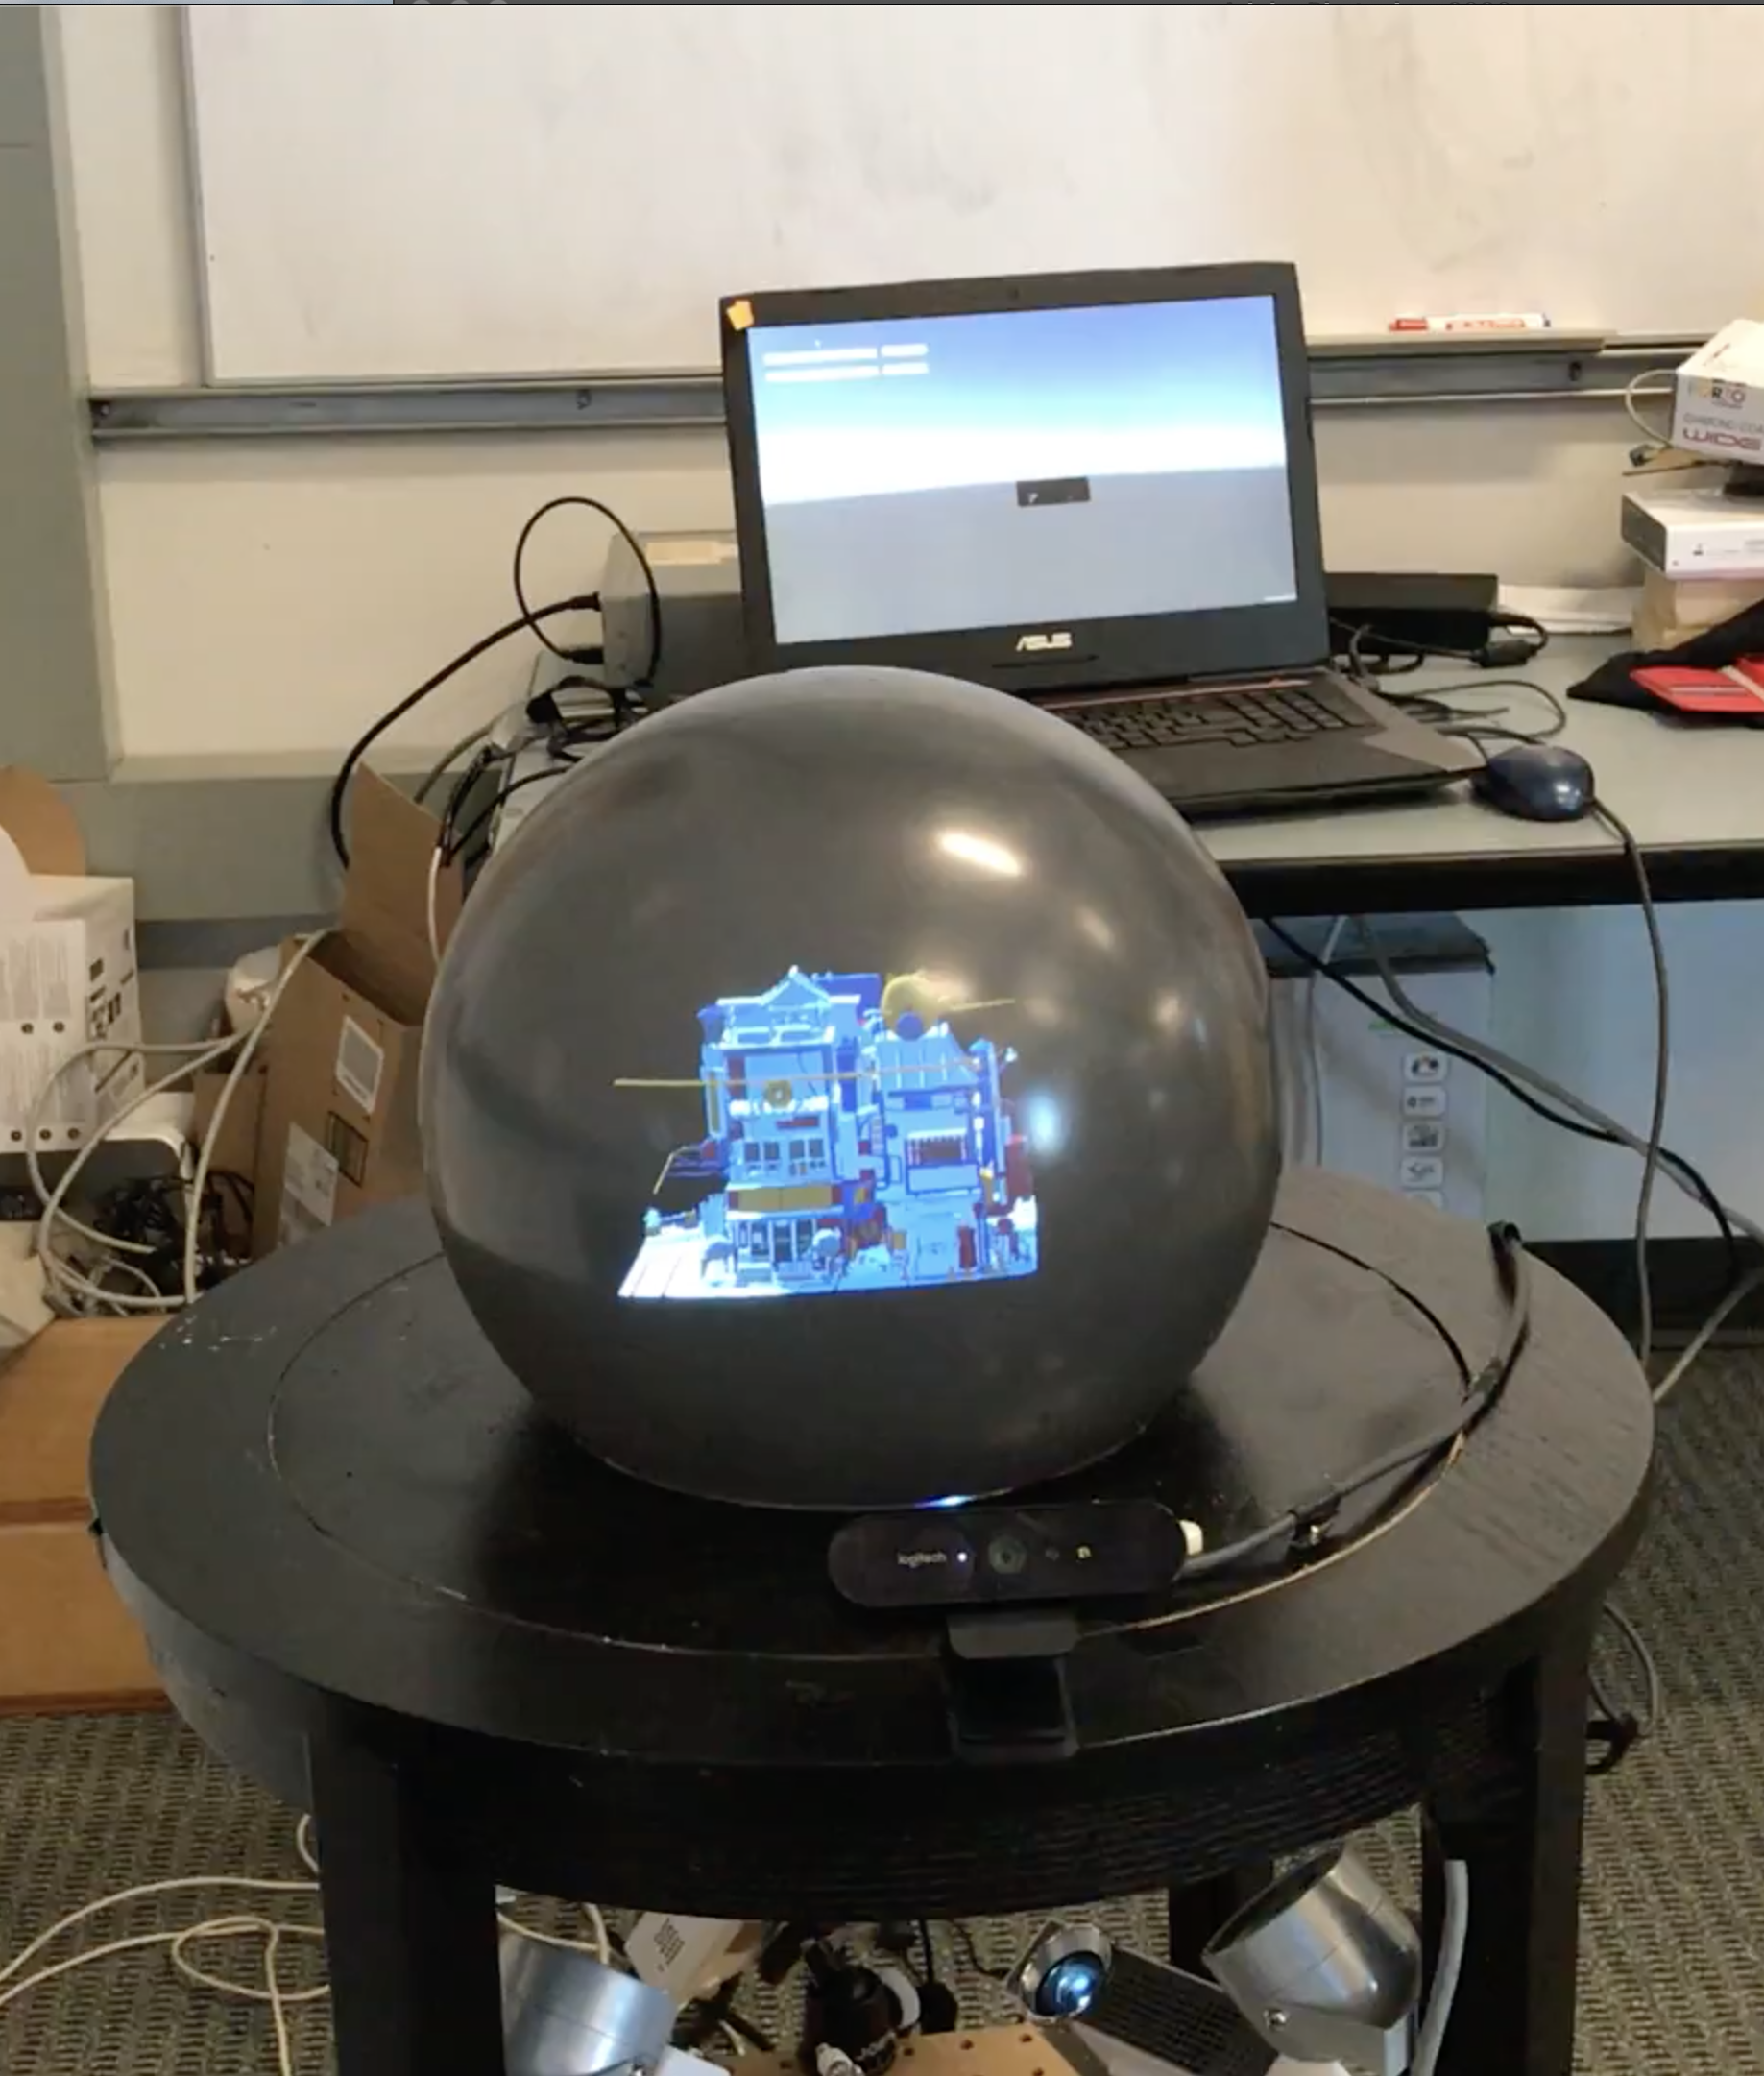
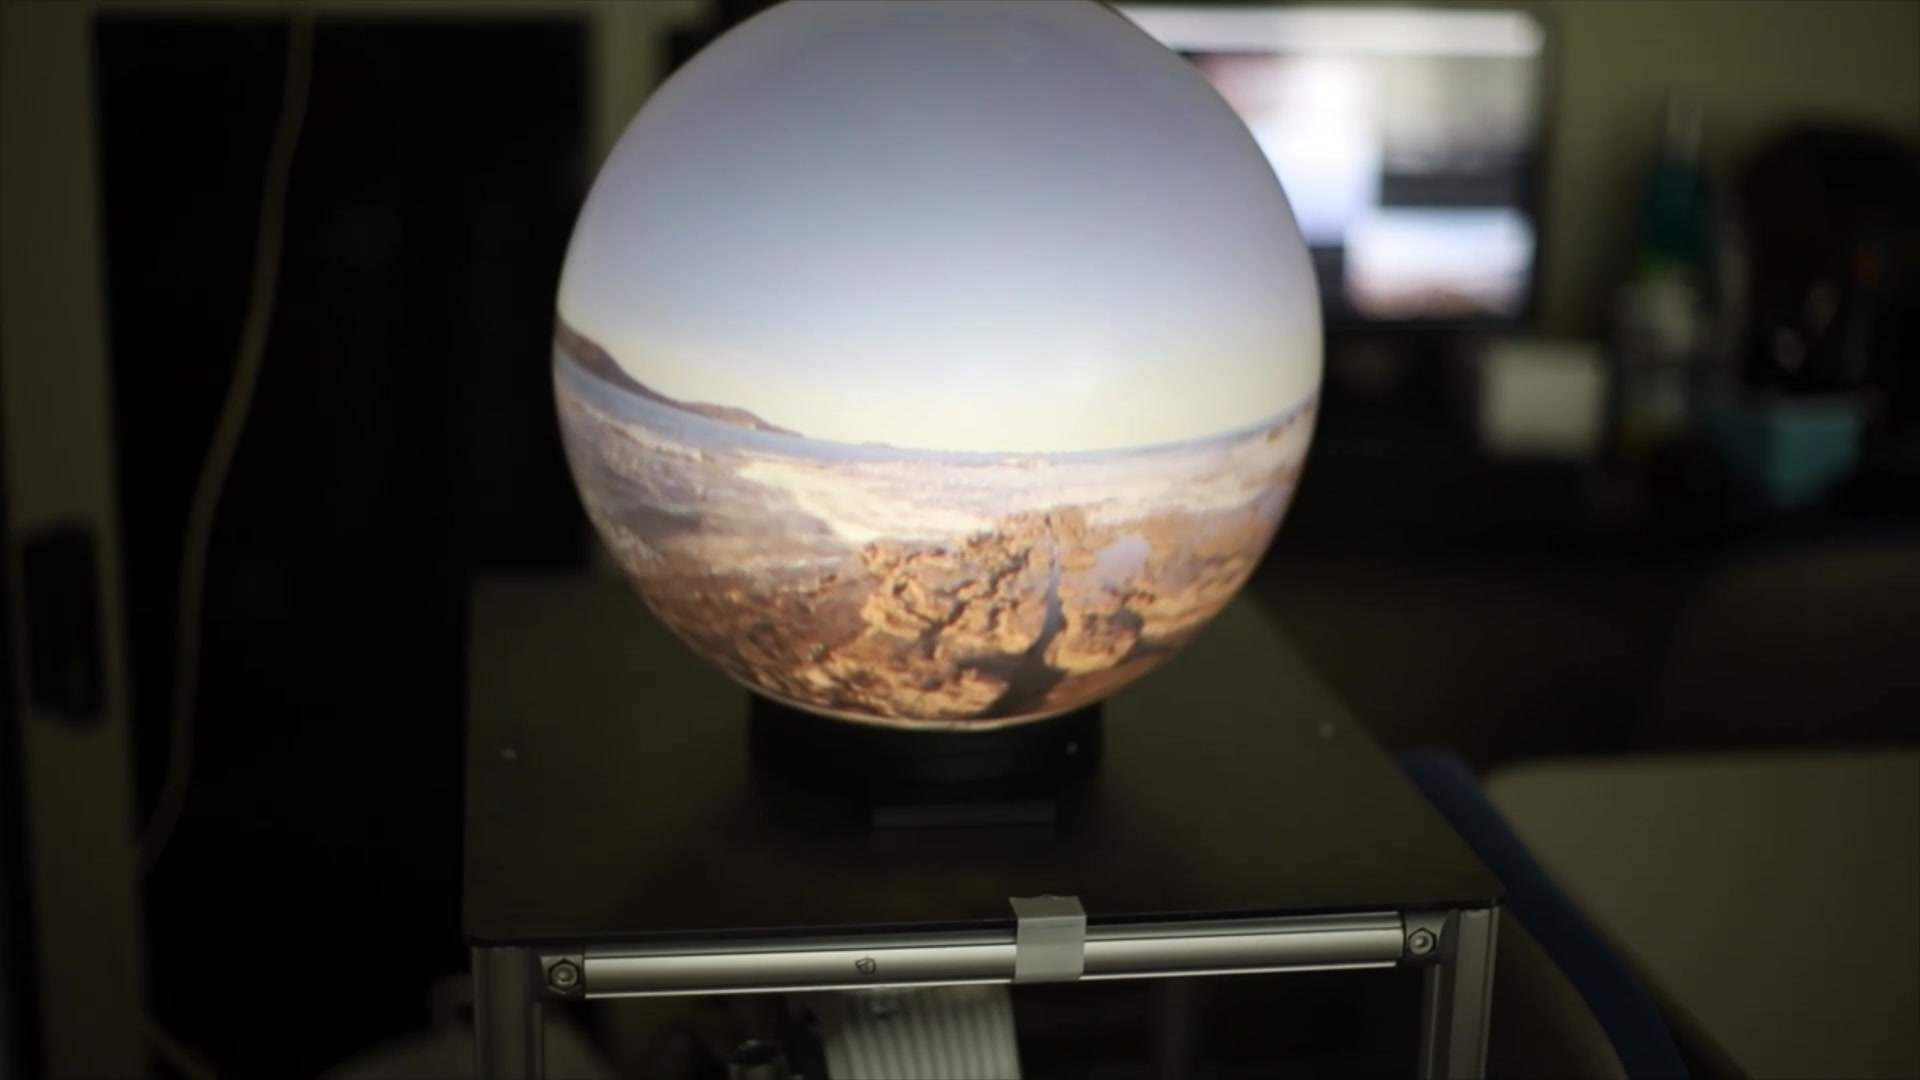
From Kunohe Castle VR and ILC visualization to the SpheriCul spherical display. Below are four moving demonstrations from the original SpheriCul website.
These are the original SpheriCul animations. Press play to watch each demonstration.